


TL;DR:
- Duplicate content appears when identical or similar text blocks exist across multiple URLs in a website or domain. Most duplicate content results from technical issues like URL parameters, filters, session IDs, or domain variations, not deliberate copying. Fixing it involves using redirects, canonical tags, and noindex directives to improve search rankings and site structure.
Duplicate content is defined as substantive blocks of text that appear identically or very similarly across multiple URLs, either within the same website or across different domains. Approximately 29% of internet pages contain duplicated content, making this one of the most widespread technical SEO problems on the web. That scale means your site almost certainly has some form of it, whether you know it or not. Understanding what is duplicate content, why it happens, and how to fix it gives you a direct path to better search rankings and cleaner site architecture.
What is duplicate content and why does it matter for SEO?
Google defines duplicate content as substantive blocks of text within or across domains that either match other content completely or are appreciably similar, including AI-generated variations and pages that serve the same intent without unique value. The industry term for this problem is “content duplication,” and it covers everything from two product pages with nearly identical descriptions to an entire article republished on a second domain.
The SEO impact is real. When search engines find multiple pages with the same content, they must decide which version to show in results. That decision process splits the ranking signals, such as backlinks and engagement, across multiple URLs instead of concentrating them on one strong page. The result is ranking dilution, where no single version performs as well as it could.
Content creators and website owners often assume duplicate content triggers a manual penalty from Google. That assumption is mostly wrong, but the actual consequences are still costly. Wasted crawl budget, split link equity, and suppressed rankings are serious problems even without a formal penalty attached.
What causes duplicate content on your website?
Most duplicate content stems from unintentional technical configuration rather than deliberate plagiarism. That distinction matters because the fix is usually technical, not editorial.
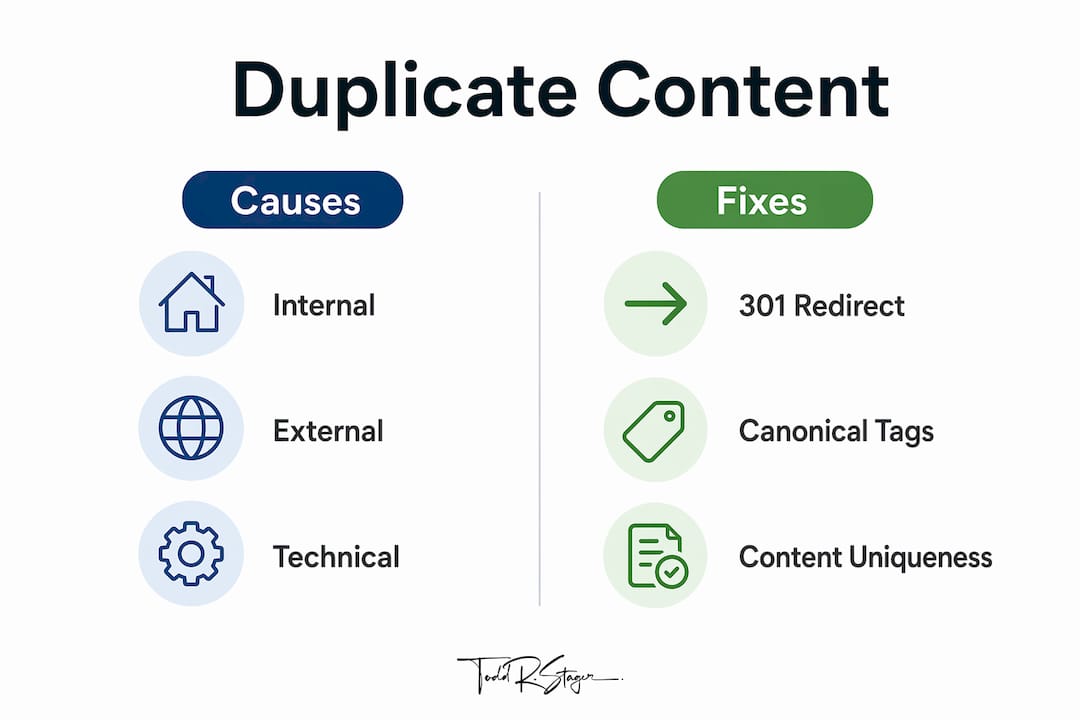
Internal causes
These are the most common sources of content duplication on a single website:
- URL parameters: Tracking codes, sorting filters, and session IDs create new URLs for the same page. A product page at
/shoesbecomes/shoes?color=red&sort=price, and both URLs serve identical content. - Faceted navigation: E-commerce sites with filtering systems can generate thousands of URL combinations from a single category page.
- Session IDs: Some content management systems append unique session identifiers to URLs, creating a new URL for every visitor.
- HTTP vs. HTTPS and www vs. non-www: If your server responds to all four versions of your domain, you have four copies of every page.
- Pagination: Pages 2, 3, and 4 of a blog archive often share large blocks of boilerplate text with page 1.
- Boilerplate text: Headers, footers, sidebars, and legal disclaimers repeat across every page. Search engines generally ignore these when evaluating uniqueness, so the real risk lies in the main content area.
External causes
External duplication happens when your content appears on other domains. Legitimate content syndication, where you publish your article on a partner site or news aggregator, creates an external duplicate. Scraping, where another site copies your content without permission, creates the same technical problem with a very different intent behind it. Both scenarios require different responses, which the section on external content covers in detail.
Pro Tip: Check your site for the four domain variants (http, https, www, non-www) by typing each into your browser. If all four load without redirecting to one canonical version, you have an immediate duplication issue to fix.
How does Google detect and handle duplicate content?
Google groups duplicate URLs into “canonical clusters” and selects one representative URL to index and rank. The other URLs in the cluster get suppressed. Google does not index them, and it reduces how often it crawls them to conserve resources.
Google’s John Mueller confirmed in april 2026 that Google does not apply ranking penalties for multiple URLs pointing to the same content. Instead, Google chooses a canonical representative URL and reduces crawl frequency of duplicates to conserve resources. The practical consequence is not a penalty but a loss of efficiency and ranking potential.
The canonicalization process works like this: Google’s crawler discovers multiple URLs with matching or near-matching content. It evaluates signals like internal linking patterns, sitemap inclusion, and any rel=canonical tags you have set. It then designates one URL as the canonical and consolidates ranking signals to that version.
The problem for large sites is crawl budget. Many large sites unintentionally create thousands of duplicate URLs via faceted navigation or URL parameters. When Google’s crawler spends its budget on those redundant pages, it has less capacity to discover and index your genuinely new content. That delay in indexing is a concrete, measurable cost.
Pro Tip: Use Google Search Console’s “Pages” report under Indexing to find URLs marked as “Duplicate, Google chose different canonical than user.” That list tells you exactly where your canonicalization signals are failing.
How to fix duplicate content: a step-by-step approach
Fixing content duplication requires a combination of technical directives and content strategy. Industry-standard methods include 301 redirects, rel=canonical tags, and noindex meta tags, and each tool has a specific use case.
Audit your site with a crawler tool. Tools that flag pages at an 85% similarity threshold in text, title tags, or meta descriptions give you a prioritized list of problem pages. Start there before making any changes.
Implement 301 redirects for consolidated pages. When you have two URLs serving the same content and you want to keep only one, redirect the secondary URL permanently to the primary. This passes link equity and eliminates the duplicate cleanly.
Apply rel=canonical tags correctly. Add a
<link rel="canonical" href="[preferred URL]">tag in the<head>of duplicate pages. This tells Google which version you want indexed without removing the other URL from your server.Add self-referencing canonical tags. Self-referencing canonical tags act as an insurance policy during site migrations or URL structure changes. Every page should declare itself as its own canonical unless it is intentionally pointing elsewhere.
Use noindex on necessary but non-unique pages. Tag/category archive pages, search results pages, and print-friendly versions of articles often duplicate content without adding unique value. A
<meta name="robots" content="noindex">tag keeps them accessible to users but removes them from the index.Handle URL parameters in Google Search Console. The URL Parameters tool lets you tell Google how to handle specific parameters, whether to ignore them or treat them as creating unique content.
Rewrite thin or templated content. When two pages cover the same topic with minimal variation, the cleanest long-term fix is making one of them genuinely different. Each page should provide unique, substantive value to avoid self-competition and ranking dilution.
The table below summarizes which fix applies to each common scenario.
| Scenario | Recommended fix |
|---|---|
| Two URLs, same content, keep one | 301 redirect from secondary to primary |
| Syndicated content on your own site | rel=canonical pointing to original |
| Category/tag archive pages | noindex meta tag |
| URL parameters creating variants | Canonical tag or Search Console parameter settings |
| HTTP/HTTPS or www/non-www variants | 301 redirect all to one preferred version |
A useful resource for small business owners working through this process is the website content checklist from Charles Creative, which covers content organization steps that reduce duplication risk from the start.
How to handle duplicate content from external sources
External duplication splits into two categories: content you syndicate intentionally and content others copy without permission. Each requires a different response.
When you syndicate your content to another publication, the risk is that Google indexes the syndicated version instead of your original. The standard fix is to ask the publisher to add a rel=canonical tag on their version pointing back to your original URL. Most reputable publishers will do this. If they will not, request a noindex tag on their version instead.
When someone scrapes your content without permission, the recommended first step is direct outreach. Professional outreach to the offending site often leads to amicable removal or addition of noindex tags without resorting to legal threats. A polite, factual email citing the original publication date and URL resolves most cases.
For monitoring external duplication, the most practical approach involves:
- Setting up Google Alerts for unique phrases from your key pages
- Periodically searching for verbatim sentences from your most important content
- Checking your Google Search Console coverage report for unexpected canonical overrides, which can signal that Google has found an external copy it prefers over yours
The risks of ignoring uncontrolled external duplicates are real. If a high-authority site copies your content and Google indexes their version as the canonical, your original page loses the ranking credit it earned. Catching this early and requesting a canonical correction protects your investment in original content. For more on common SEO mistakes that compound duplication problems, Toddstager’s SEO essentials guide covers the full picture.
Key Takeaways
Fixing duplicate content is primarily a technical SEO task, and the most effective approach combines canonical tags, 301 redirects, and noindex directives with a commitment to creating genuinely unique page content.
| Point | Details |
|---|---|
| Duplication is widespread | Approximately 29% of web pages contain duplicated content, making audits a priority for every site. |
| No direct penalty, but real costs | Google suppresses duplicate URLs and reduces crawl frequency, which wastes budget and dilutes rankings. |
| Technical causes dominate | URL parameters, session IDs, and faceted navigation create most duplicate content unintentionally. |
| Three core fixes | Use 301 redirects, rel=canonical tags, and noindex meta tags based on the specific duplication scenario. |
| External copies need active monitoring | Set up alerts and request canonical corrections from sites that republish or scrape your content. |
What I’ve learned about duplicate content after years of SEO work
The biggest mistake I see website owners make is treating duplicate content as purely a content problem. They spend hours rewriting product descriptions when the real issue is a URL parameter configuration that is generating 500 near-identical pages behind the scenes. Technical SEO configuration issues have more impact on site-wide duplicate problems than content rewriting alone. Fix the architecture first, then refine the content.
I’ve also seen the boilerplate panic. Owners notice that their header and footer text appears on every page and assume they have a massive duplication crisis. Search engines largely ignore repeated boilerplate when evaluating page uniqueness. The focus should stay on the main content area of each page, not the navigation elements.
For large e-commerce sites with faceted navigation, the crawl budget issue is the one that keeps me up at night. A site with 10,000 products and 15 filter combinations per category can generate hundreds of thousands of duplicate URLs. Google’s crawler will exhaust its budget on those pages and never reach new product listings. Canonical tags and robots directives on filter pages are not optional on sites like that. They are the difference between your new inventory getting indexed in days versus months.
The SEO best practices for service websites I recommend always start with a duplication audit before any content work begins. You cannot build on a foundation with cracks in it.
— TODD
Toddstager’s technical SEO expertise can resolve your duplication issues
Duplicate content problems range from a single redirect fix to a full-scale canonical architecture overhaul across thousands of pages. Toddstager works with businesses across industries, from e-commerce growth strategies to local service providers, to identify and resolve the specific duplication issues holding their sites back.
Toddstager’s site audits cover URL parameter handling, canonical tag implementation, redirect chains, and content uniqueness scoring. Every recommendation is tied to a measurable ranking outcome, not a generic checklist. If your site has indexing gaps, ranking dilution, or crawl budget waste from duplicate pages, a targeted audit is the fastest way to find and fix the root cause. Reach out to Toddstager to get a clear picture of where your site stands.
FAQ
What is the duplicate content definition in SEO?
Duplicate content is substantive text that appears identically or very similarly across multiple URLs, either on the same site or across different domains. Google evaluates both exact matches and near-duplicate pages that serve the same search intent without unique value.
Does duplicate content cause a Google penalty?
Google does not apply a direct ranking penalty for duplicate content. Instead, it selects one canonical URL to rank and suppresses the others, which reduces crawl frequency and can dilute ranking signals across multiple pages.
How do I identify duplicate content on my site?
Crawler tools flag pages with an 85% or higher similarity threshold in text, title tags, or meta descriptions. Google Search Console’s Indexing report also shows URLs where Google chose a different canonical than the one you specified.
What is the fastest way to fix duplicate content?
The fastest fix depends on the cause. Use a 301 redirect when consolidating two URLs into one, apply a rel=canonical tag when you need both URLs to remain accessible, and add a noindex tag to archive or filter pages that duplicate content without adding unique value.
How does content syndication create duplicate content issues?
When your article is republished on another site without a canonical tag pointing back to your original URL, Google may index the syndicated version instead of yours. Request that the publisher add a rel=canonical tag on their version referencing your original page to protect your ranking credit.
Recommended
- SEO Essential – Chapter 13 – COMMON SEO MISTAKES, BEST PRACTICES, AND CONTENT MANAGEMENT – Todd Stager
- SEO Essential – Chapter 11 – CONTENT MARKETING, SEO, AND GOOGLE’S HELPFUL CONTENT UPDATE – Todd Stager
- The Role of Content Freshness in SEO and AI Rankings
- SEO Essentials – Chapter 7 – TECHNICAL SEO AND THE ANATOMY OF PERMALINKS – Todd Stager