


A robots.txt file is a plain text file that sits at the root of your website and tells web crawlers which pages or sections they are allowed to visit. It operates under the Robots Exclusion Protocol, a voluntary standard formalized as RFC 9309, and is recognized by every major search engine including Google. Think of it as a set of house rules posted at your front door: well-behaved bots read them and comply, but the file itself cannot physically stop anyone from walking in.
Here is what a robots.txt file does in practice:
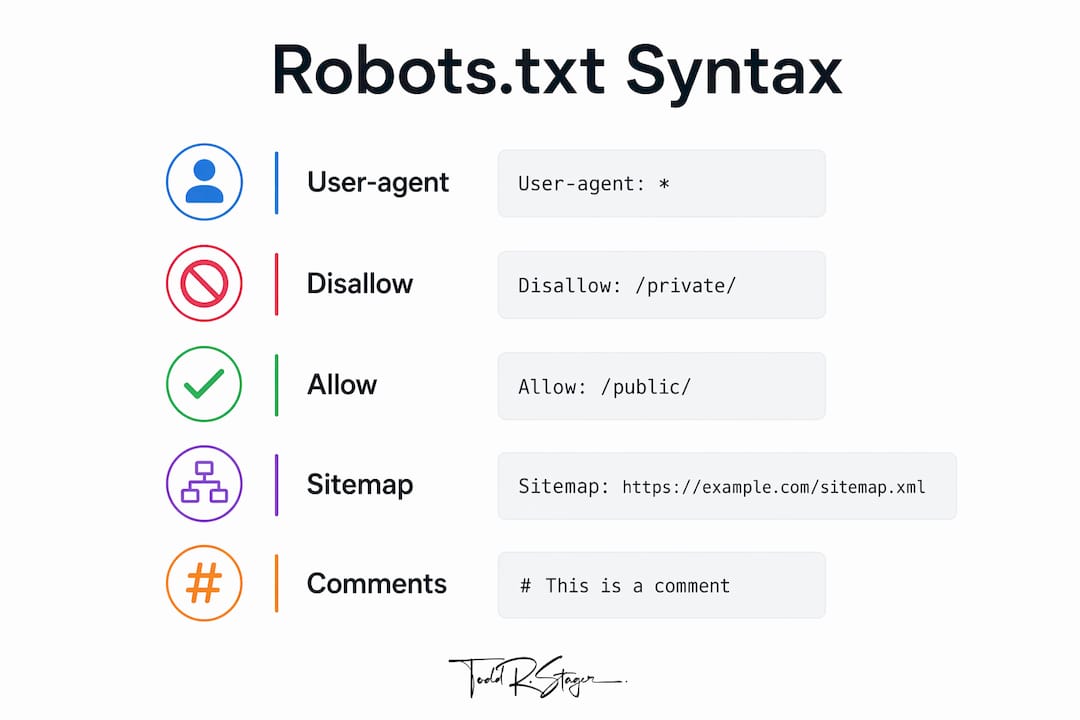
- User-agent: Identifies which crawler the rule applies to (e.g., Googlebot, or all bots using
*) - Disallow: Tells a crawler which paths it should not visit
- Allow: Explicitly permits access to a path, even within a disallowed directory
- Sitemap: Points crawlers to your XML sitemap for more efficient indexing
Two things the file does not do: guarantee that every bot complies, and block pages from appearing in search results. Robots.txt controls crawling, not indexing. A page you disallow can still show up in Google’s results if another site links to it. For true content exclusion, you need a noindex meta tag or password protection.
How robots.txt files work: syntax, structure, and key directives
The file uses a straightforward line-by-line syntax. Each block of rules starts with a User-agent declaration, followed by one or more Disallow or Allow directives. A blank line separates rule blocks for different crawlers.
Basic structure:
User-agent: *
Disallow: /private/
Allow: /public/
Sitemap: https://example.com/sitemap.xml
The * wildcard in User-agent applies the rules to all crawlers. You can target a specific bot by name, such as Googlebot or GPTBot, and give it different instructions than everyone else.
How crawlers interpret rules:
When a crawler encounters multiple matching rules, it applies the most specific one. Google’s crawlers follow the longest matching path rule: if you have Disallow: / and Allow: /public/, the more specific Allow wins for anything inside /public/. This precedence logic is why a single misplaced character can create unintended consequences.
Pro Tip: Never use robots.txt to hide sensitive data. Malicious bots can read your robots.txt file and use the disallowed paths as a roadmap to find exactly what you are trying to protect. Use authentication and server-level access controls for anything genuinely confidential.
Supported directives at a glance:
| Directive | Function | Example |
|---|---|---|
User-agent | Targets a specific crawler or all crawlers | User-agent: Googlebot |
Disallow | Blocks a crawler from a path | Disallow: /admin/ |
Allow | Permits access within a disallowed directory | Allow: /admin/public/ |
Sitemap | Declares the sitemap URL | Sitemap: https://example.com/sitemap.xml |
Crawl-delay | Suggests a pause between requests | — |
One distinction worth keeping clear: Disallow blocks crawling, not indexing. If you want a page removed from search results, a Disallow rule alone will not accomplish that. Disallowed pages can still appear in search results when external sites link to them, often showing up with no description or snippet. The noindex directive in a page’s HTML meta tags is the correct tool for keeping pages out of search results entirely.
Pro Tip: Use Google Search Console’s URL Inspection tool alongside the robots.txt tester to verify that your directives are working as intended before pushing changes to a live site.
Real-world robots.txt examples you can use right now
Seeing the syntax in context makes it click faster than any abstract explanation. Here are practical examples covering the most common scenarios website owners face.
Minimal file: allow everything, declare your sitemap
User-agent: *
Disallow:
Sitemap: https://example.com/sitemap.xml
An empty Disallow line means no restrictions. This setup is useful for small sites that want to signal cooperation to crawlers while pointing them directly to the sitemap. It also eliminates the 404 log noise that occurs when bots request a missing robots.txt file.
Block admin and login pages
User-agent: *
Disallow: /wp-admin/
Disallow: /wp-login.php
Disallow: /cart/
Disallow: /checkout/
Sitemap: https://example.com/sitemap.xml
This is the standard configuration for most WordPress and e-commerce sites. Cart and checkout pages carry no SEO value and consume crawl budget that could go toward product or service pages. Blocking them keeps Googlebot focused on content that actually drives rankings.
Block parameterized URLs and internal search results
User-agent: *
Disallow: /search?
Disallow: /?s=
Disallow: /tag/
Disallow: /filter/
Sitemap: https://example.com/sitemap.xml
Internal search result pages and filter combinations can generate thousands of near-duplicate URLs. Search engines do not need to crawl every variation of /products?color=red&size=M&sort=price. Blocking these paths protects crawl budget and reduces the risk of duplicate content penalties.
Block AI training crawlers
User-agent: GPTBot
Disallow: /
User-agent: CCBot
Disallow: /
User-agent: *
Disallow: /admin/
Sitemap: https://example.com/sitemap.xml
Blocking AI crawlers like GPTBot (OpenAI) and CCBot (Common Crawl) has become a practical concern for content creators and businesses that do not want their material used for AI model training. These bots follow the Robots Exclusion Protocol, so a Disallow: / rule for their user-agent strings is effective.
Staging site: block everything
User-agent: *
Disallow: /
A staging or development environment should never be indexed. This single-rule file tells every crawler to stay out entirely. Pair it with a password on the staging server for real protection, since robots.txt alone is not a security barrier.
Pro Tip: When you block admin paths and internal search results, always verify that you have not accidentally blocked CSS or JavaScript files that Googlebot needs to render your pages. Rendering failures can suppress rankings even when the pages themselves are technically accessible.
Is a robots.txt file necessary? Its importance and limits
For a small, simple website with a handful of pages, a robots.txt file is not required. Google’s own guidance confirms that small sites with uncomplicated content can rely on automatic crawling and indexing without one. If your site is a five-page portfolio or a local service page, Google will find and index your content without any instruction file.
The calculus changes as a site grows. For e-commerce platforms, news sites, or any property with thousands of URLs, robots.txt becomes a practical tool for managing crawl budget. Search engine crawlers allocate a finite number of requests to each site per day. Spending those requests on cart pages, duplicate filter URLs, or staging directories means fewer requests for the product and service pages that generate revenue. Managing crawl budget through robots.txt helps focus indexing on high-value content.
When robots.txt genuinely helps your site:
- Large e-commerce sites with faceted navigation generating duplicate URLs
- Sites with staging or development directories on the same domain
- Platforms with user-generated content that should not be indexed
- Any site wanting to block AI training crawlers by user-agent
- Properties with admin panels, login pages, or internal tools exposed at crawlable paths
What robots.txt cannot do:
- Block a page from appearing in search results (use
noindexfor that) - Prevent malicious bots from accessing your site
- Protect sensitive data (use server-level authentication)
- Guarantee compliance from any crawler
The voluntary nature of the standard is its most misunderstood aspect. RFC 9309 formalizes robots.txt as a code of conduct, not a technical enforcement mechanism. Google, Bing, and other reputable search engines comply reliably. Scrapers and malicious crawlers do not.
A misconfigured robots.txt can cause real damage. Accidentally blocking your CSS and JavaScript files prevents Googlebot from rendering your pages correctly, which can suppress rankings across your entire site. Testing changes with Google Search Console’s robots.txt tester before publishing is the single most important habit you can build around this file.
How to find, create, and edit your robots.txt file
Finding your robots.txt file takes about three seconds. Append /robots.txt to your domain in any browser, for example https://example.com/robots.txt. If a file exists, it displays as plain text. If you see a 404 error, no file is present.
Creating a robots.txt file from scratch:
- Open any plain text editor (Notepad on Windows, TextEdit on Mac in plain text mode).
- Write your directives following the syntax covered above.
- Save the file as
robots.txtwith no other extension. - Upload it to the root directory of your web server, the same folder that contains your homepage’s
index.htmlorindex.php. - Verify it is accessible at
yourdomain.com/robots.txt. - Test it in Google Search Console under Settings > robots.txt.
WordPress users: check your plugin first. SEO plugins like Yoast SEO and Rank Math generate virtual robots.txt files that are served dynamically. These virtual files can override a physical robots.txt file you upload to your server, meaning your manual edits may be silently ignored. Before editing anything, check your plugin’s settings to see whether it controls the robots.txt output. If it does, make your changes there rather than in a physical file.
Safe editing checklist:
- Back up the current file before making any changes
- Test each new directive in Google Search Console before publishing
- Confirm that CSS, JavaScript, and image directories are not blocked
- Verify the sitemap URL in the file is correct and accessible
- Check the file after any major CMS or plugin update, since updates can overwrite your settings
For sites managed through a CMS like Shopify or Squarespace, the platform controls robots.txt access. Shopify, for example, generates its own robots.txt file and offers limited customization through its Liquid template system.
Troubleshooting common robots.txt issues and mistakes
Most robots.txt problems fall into a small number of categories, and nearly all of them are fixable once you know where to look.
Frequent issues and how to fix them:
- Accidental full-site block: A
Disallow: /underUser-agent: *blocks every crawler from your entire site. This is the most damaging mistake and surprisingly common after a site migration or CMS update. Check Google Search Console’s Coverage report for a sudden spike in “Excluded” pages. - Blocked CSS and JavaScript: Googlebot needs to load your stylesheets and scripts to render pages correctly. If your robots.txt blocks
/wp-content/or/assets/, Google may see a broken version of your site. Use the URL Inspection tool in Google Search Console to check how Google renders a specific page. - Wrong file location: The file must live at the root domain, not a subdirectory.
example.com/blog/robots.txtdoes not apply toexample.com/robots.txt. Each subdomain needs its own file. - Case sensitivity errors: Paths in robots.txt are case-sensitive on most servers.
Disallow: /Admin/does not block/admin/on a Linux server. Match the exact casing of your actual URLs. - Virtual file conflicts in WordPress: If you upload a physical robots.txt file but your SEO plugin generates a virtual one, the plugin’s version usually wins. Edit through the plugin’s interface instead.
- Syntax errors: Each directive must be on its own line. A
Disallowrule on the same line asUser-agentwill be ignored. Use a robots.txt validator to catch formatting issues before they reach production.
Diagnosing “blocked by robots.txt” errors:
When Google Search Console flags a URL as “Blocked by robots.txt,” open the URL Inspection tool, enter the affected URL, and check the “Crawl” section. It will show you exactly which rule is blocking the crawler. From there, you can adjust the directive, test the fix in the robots.txt tester, and request reindexing.
For service-based businesses managing their own sites, understanding how robots.txt interacts with your overall SEO workflow prevents small configuration errors from becoming ranking problems that take months to recover from.
Expert insights on robots.txt from SEO consultant Todd Stager
Todd Stager has worked across dozens of industries, from agricultural businesses and automotive dealers to medical practices and e-commerce platforms. Across all of them, robots.txt comes up as one of the most misunderstood files on a website. Not because it is complicated, but because its limitations are routinely overstated in one direction and understated in another.
The most common misconception Todd encounters: website owners who believe a Disallow rule keeps a page out of Google’s index. It does not. Crawling and indexing are separate processes. A page you block from crawling can still appear in search results if Google learns about it through an external link. The correct tool for keeping a page out of search results is a noindex meta tag on the page itself, not a robots.txt directive.
The second misconception: that robots.txt provides security. It does not. Listing a path in your robots.txt file effectively advertises that path to anyone who reads the file. Sensitive directories need authentication, not a Disallow rule.
Practical checklist distilled from Todd’s SEO workflows:
- Audit your robots.txt file every time you launch a new site section or run a major CMS update
- Block non-indexable pages (cart, checkout, admin, login) to protect crawl budget
- Always include your sitemap URL in the robots.txt file
- Test every change in Google Search Console before pushing to production
- For WordPress sites, manage robots.txt through your SEO plugin, not a physical file
- Consider adding user-agent blocks for AI training crawlers if content ownership matters to your business
- Never use robots.txt as your only line of defense for private content
For e-commerce sites in particular, getting robots.txt right is one of the highest-leverage technical SEO tasks available. The e-commerce SEO guide from Toddstager covers crawl budget management alongside the broader indexing strategy that makes product pages rank. Small businesses managing their own sites can also find practical guidance on small business SEO budgeting that puts robots.txt in context with the rest of your technical foundation.
Whether you are running a landscaping company, a dental practice, or a regional restaurant group, the robots.txt principles are the same. Get the syntax right, test before you publish, and never confuse crawl control with content security. Those three habits cover the vast majority of robots.txt problems that Todd sees in real-site audits.
For service-based businesses looking to align their technical SEO with their marketing goals, understanding how automation shapes B2B marketing can help frame where robots.txt fits within a broader digital strategy.
If your site is growing and you want an experienced SEO consultant to audit your robots.txt file alongside your full technical setup, Toddstager works with businesses across agriculture, automotive, medical, and dozens of other industries. Start with the SEO for e-commerce guide or explore industry-specific strategies at Toddstager.com.
Key Takeaways
A robots.txt file controls which parts of your site crawlers visit, but it does not block pages from search results or provide any form of security.
| Point | Details |
|---|---|
| Crawling vs. indexing | Robots.txt blocks crawling only; use a noindex meta tag to keep pages out of search results. |
| Crawl budget management | Large and e-commerce sites benefit most from robots.txt by blocking duplicate or low-value URLs. |
| Not a security tool | Sensitive directories need server-level authentication, not a Disallow rule. |
| Test before publishing | Use Google Search Console’s robots.txt tester to catch errors before they affect live rankings. |
| WordPress plugin conflicts | SEO plugins generate virtual robots.txt files that can override physical files; edit through the plugin. |